Exercise 2: The Subterranean Divide
Time: 30 min
Previous: Exercise 1: The Arrival
Next: Exercise 3: The Flash Crash
Sarah takes you into the subterranean datacenter. One side of the room is containerized APIs; the other still runs heavy ledgers. Both will share the same SUSE Virtualization fabric. First you map the nodes, carve workspaces, set storage policy, and build the production service network the later exercises need.
Tip: The customer Rodeo image pre-creates
prod,prod/service, and an SSH key. This lab's deploy automation now pre-createsprodandprod/servicetoo, plus node labels. So 2.2 and 2.5 below are a confirm, not a create. You still register the SSH key in 2.6, since the automation only embeds the lab VM key directly into the pre-created VMs' cloud-init, not into a reusable HarvesterSSHKeyobject.
2.1 Inspect node topology and Longhorn on disk
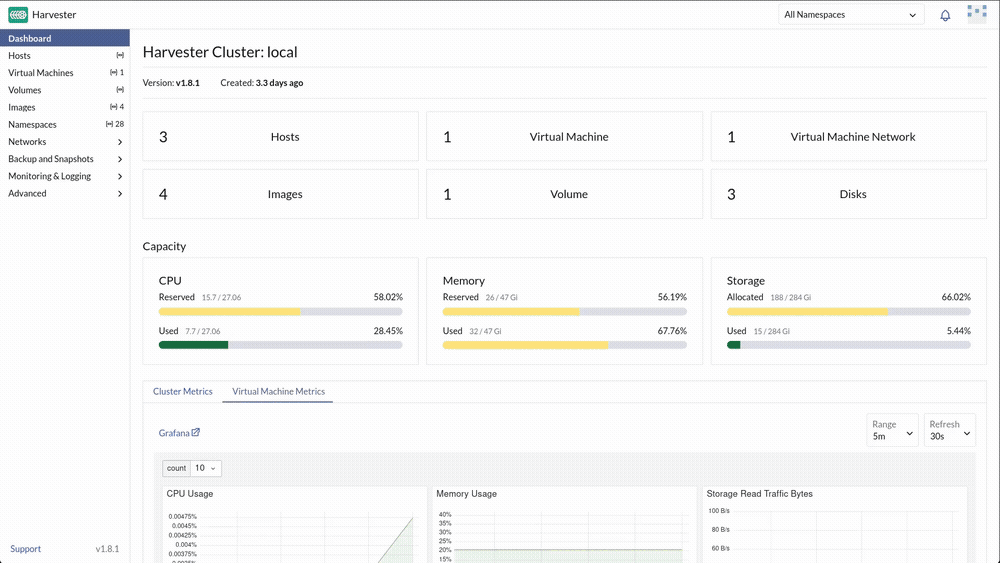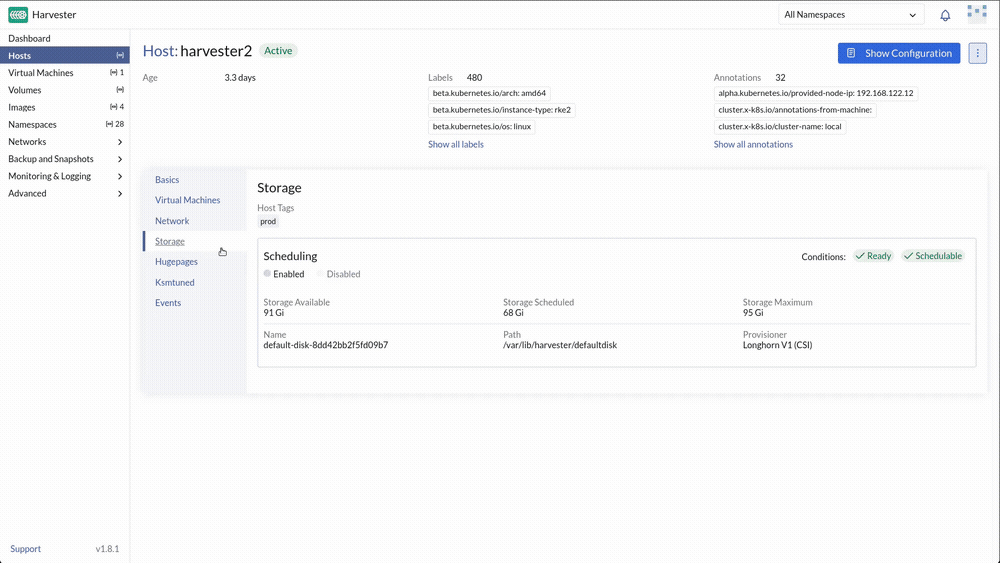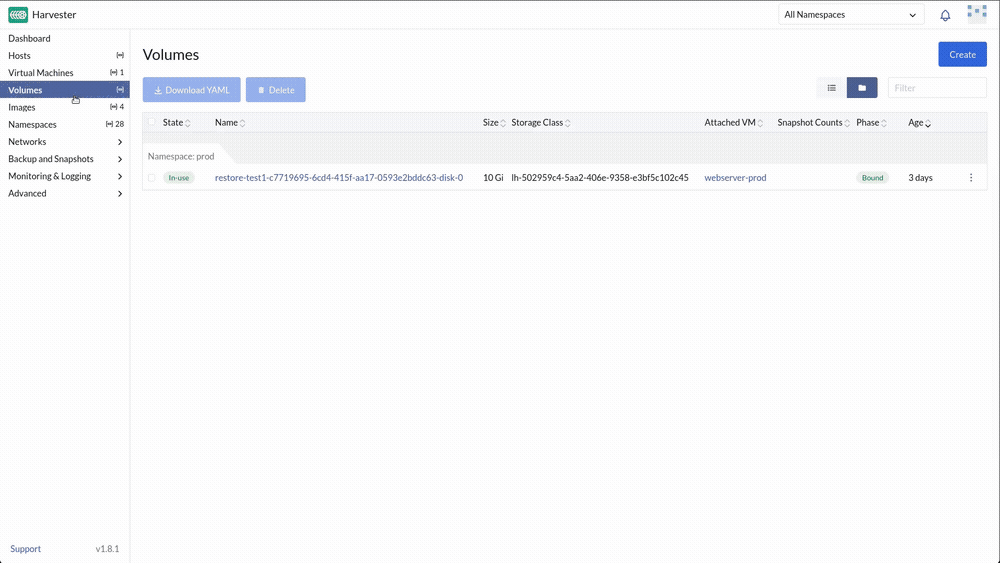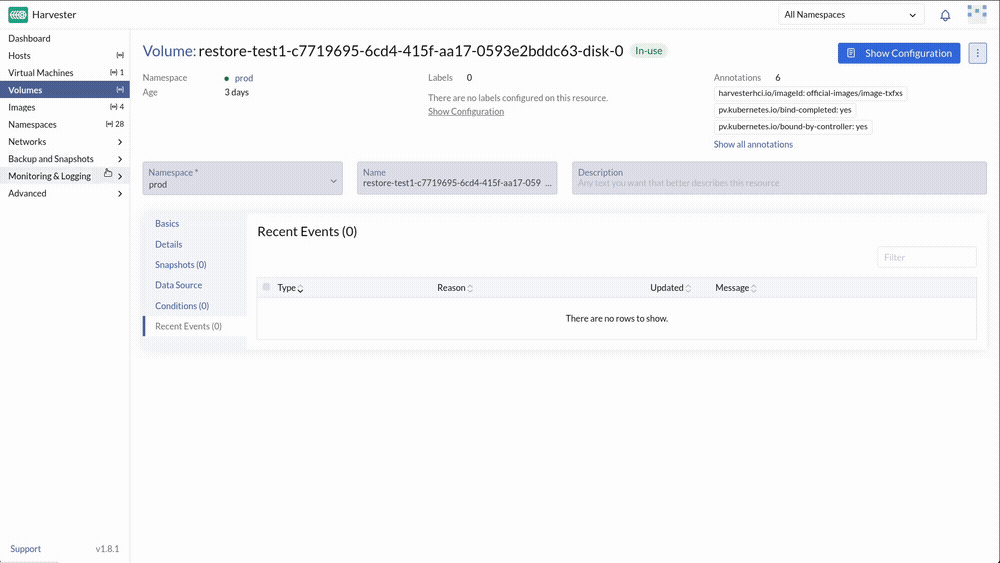
In the Harvester UI → Hosts:
- Open one host and review reserved vs used CPU/memory, IP, and disks.
- Each disk you see feeds the Longhorn pool that will hold VM volumes.
From the KVM host terminal (with the kubeconfig from Exercise 1.5):
kubectl get nodes.longhorn.io -n longhorn-system
kubectl get replicas.longhorn.io -n longhorn-system \
  -o custom-columns=REPLICA:.metadata.name,VOLUME:.spec.volumeName,NODE:.spec.nodeID
Each volume has replicas on several nodes. Replicas on disk are how Longhorn keeps VM data alive across node loss.
Deployed the lab yourself? You can see the replica files on a node's disk too:
sudo rodeo ssh harvester1, thenls /var/lib/harvester/defaultdisk/replicas/.
2.2 Confirm prod, create dev
Namespaces: prod already exists. Deploy automation created it, along with two VMs already running inside it (you'll meet them in Exercise 4). Open it and confirm it's there.
Namespaces → Create:
| Name |
|---|
dev |
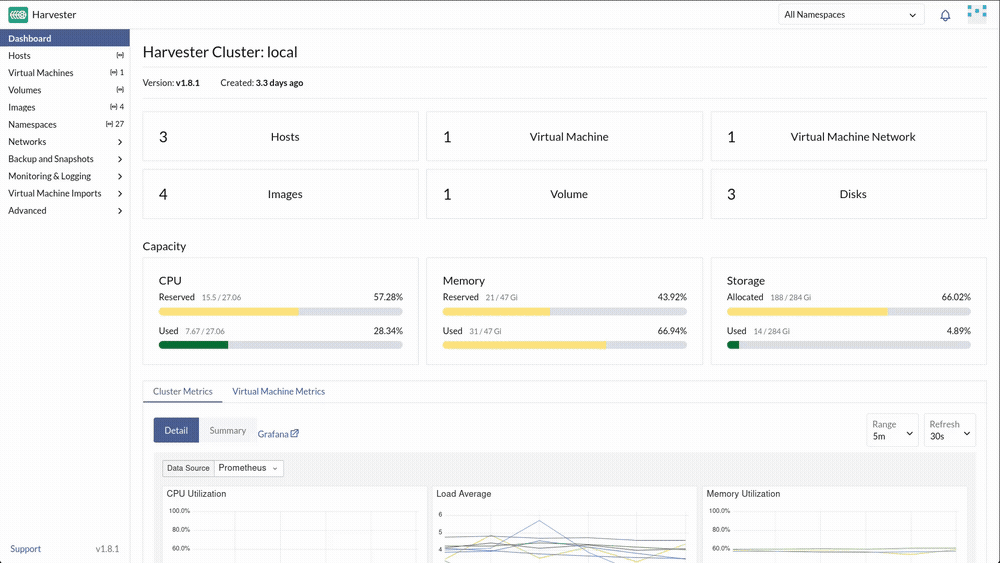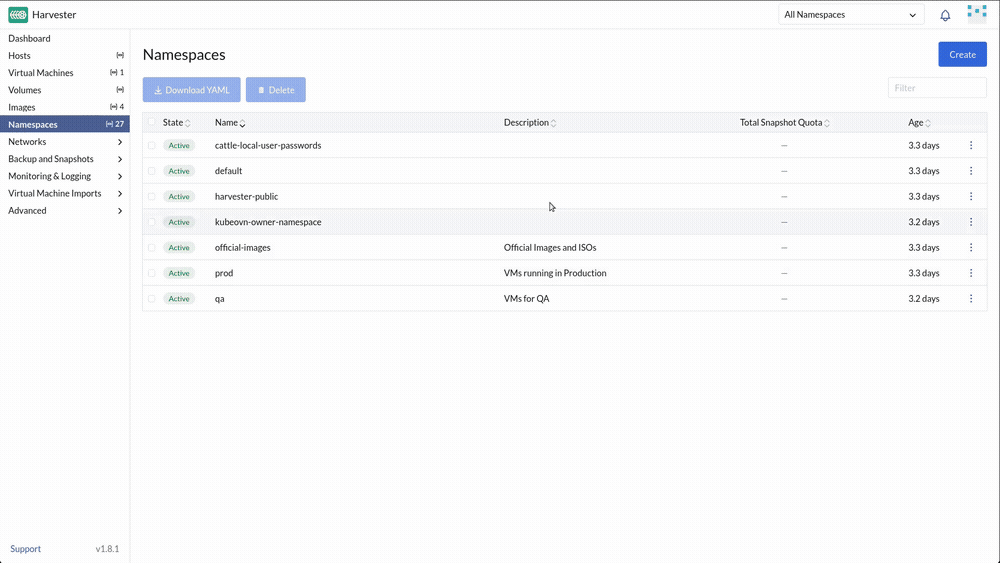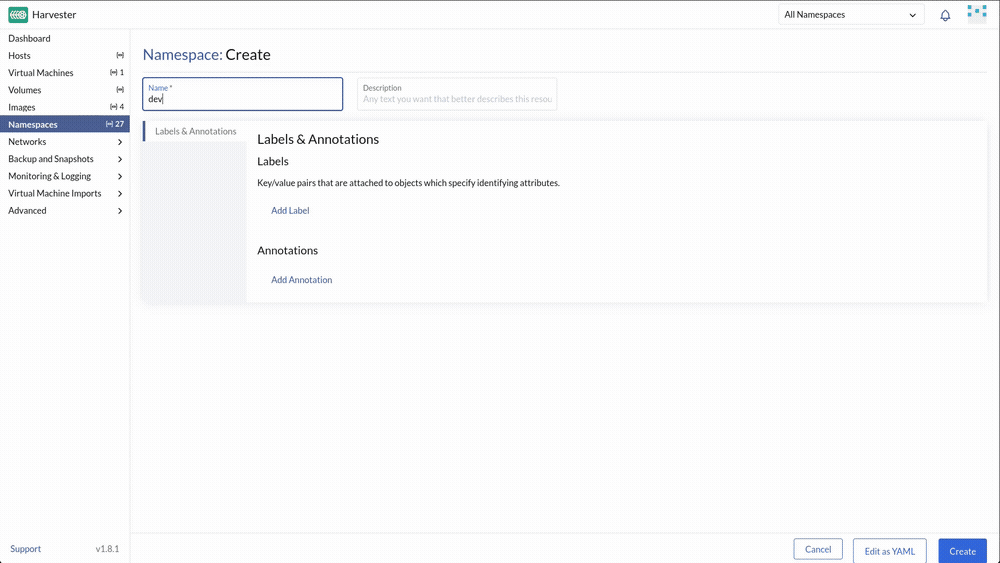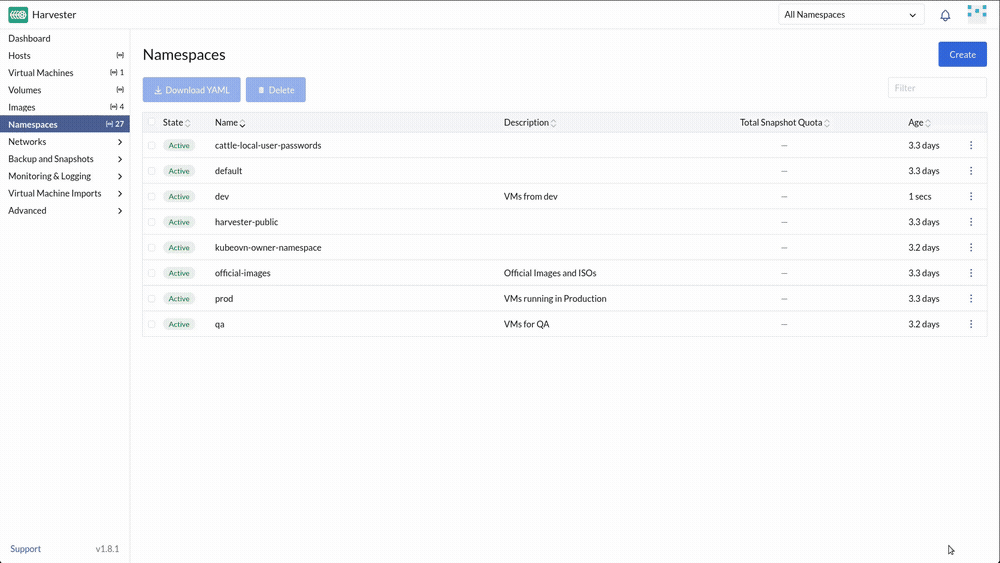
prod holds bank production VMs; dev is for cheaper sandboxes.
2.3 Understand the default storage class
Advanced → Storage Classes → open harvester-longhorn.
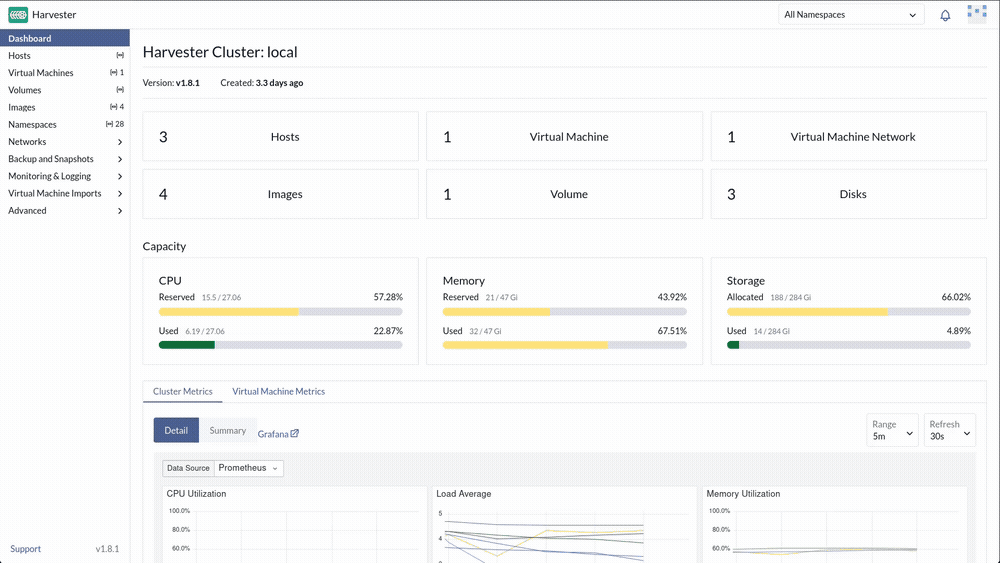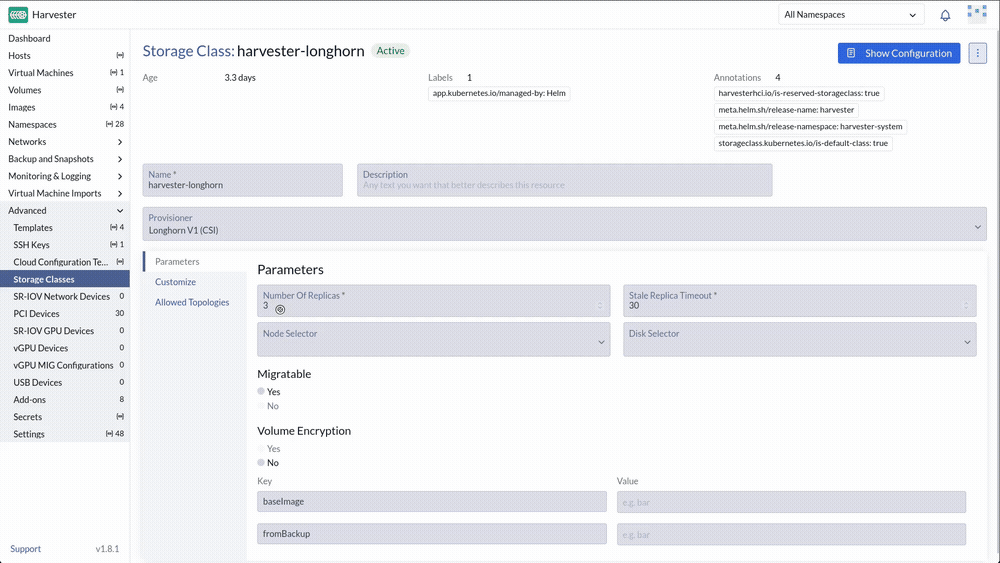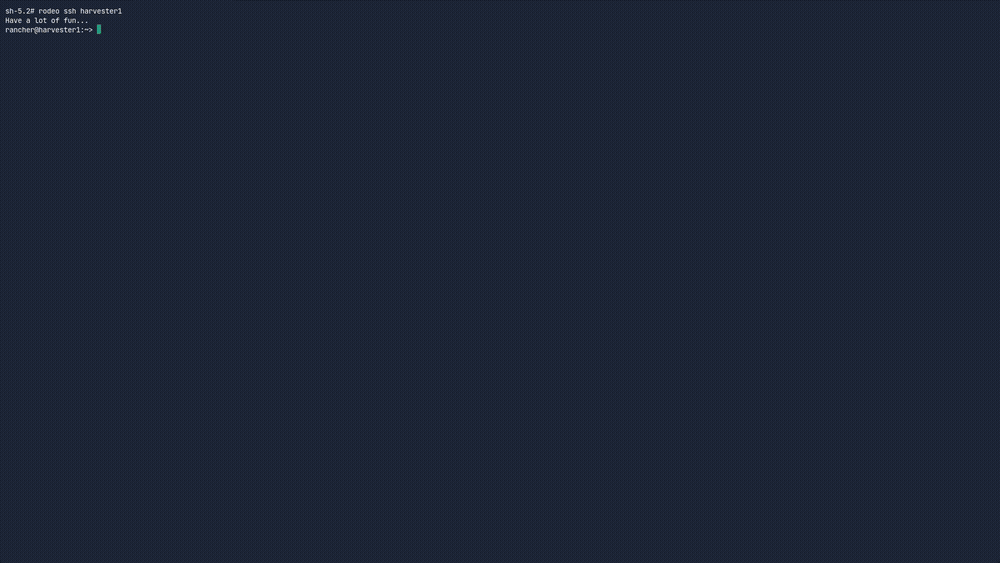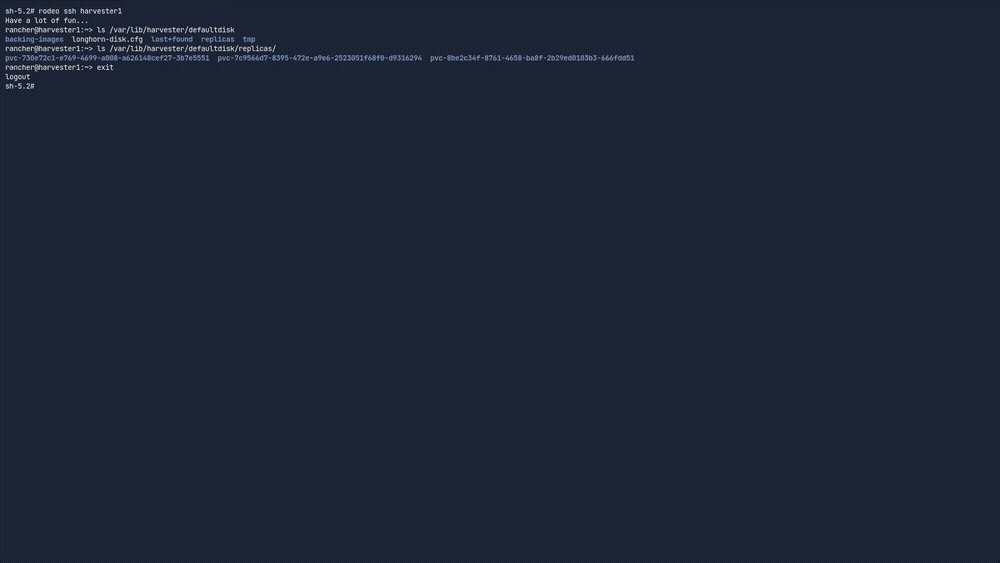
Note Number Of Replicas = 3. Production ledgers want that. Disposable quant sandboxes do not. Replica count is a policy, not a law of physics.
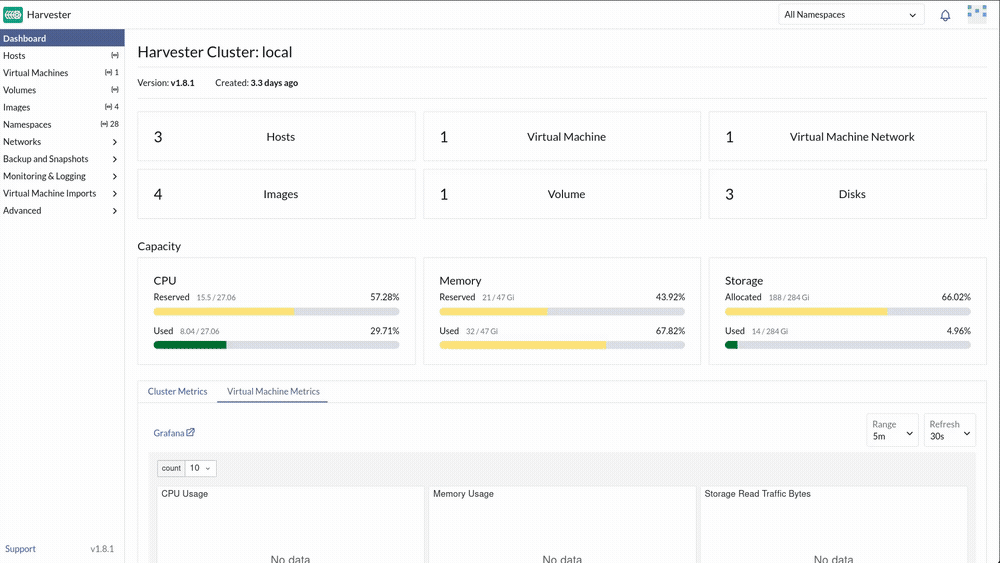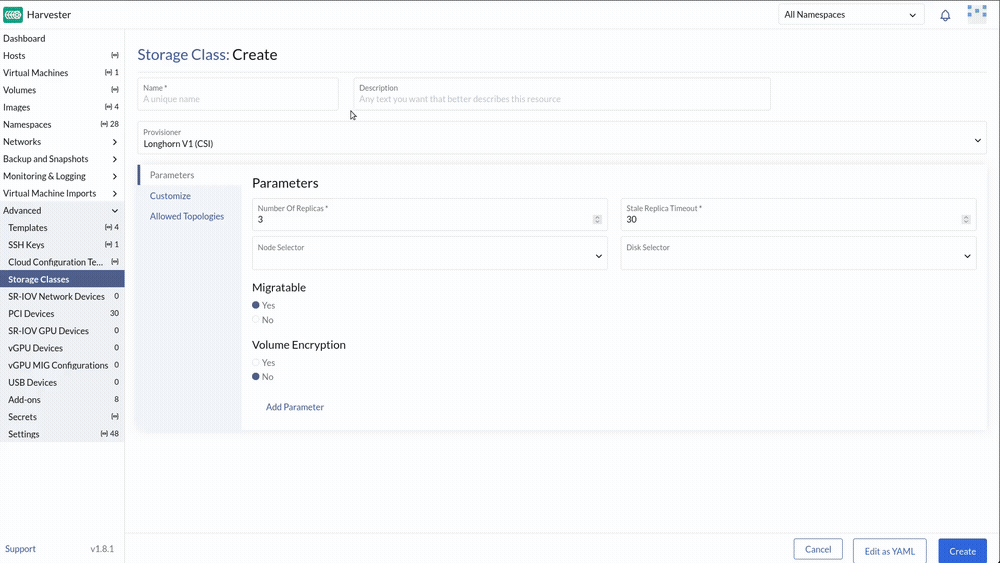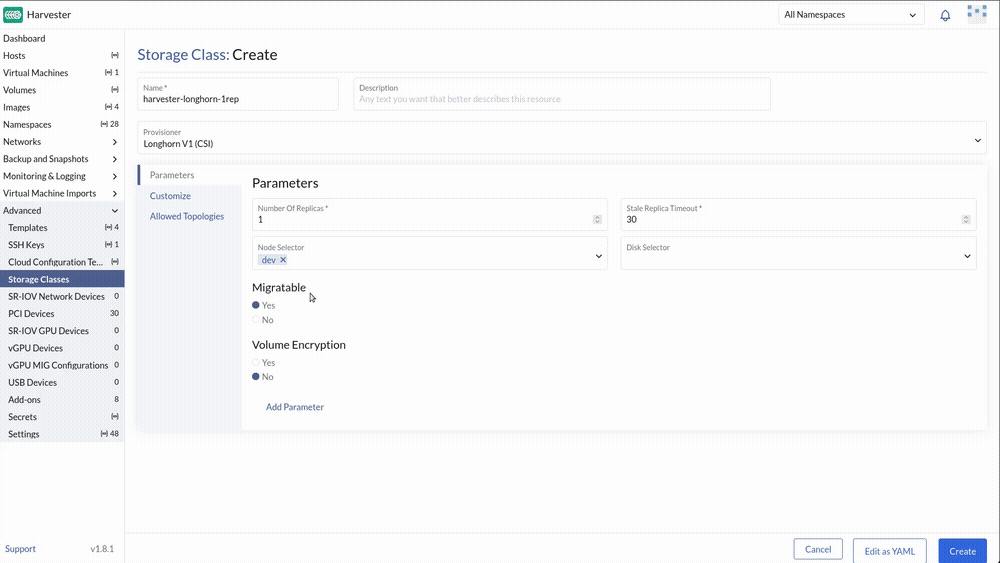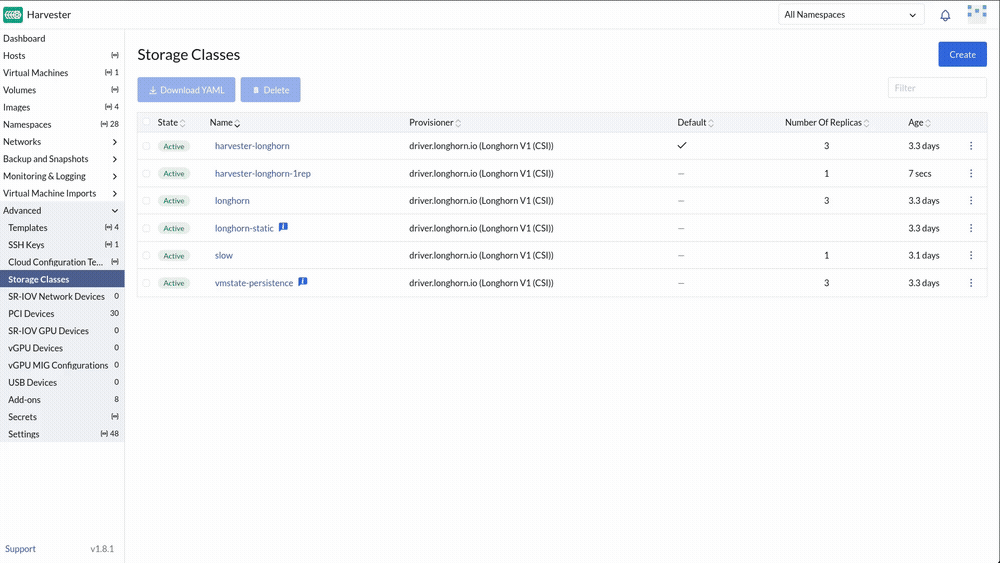
2.4 Build a cost-tier StorageClass
Advanced → Storage Classes → Create:
| Field | Value |
|---|---|
| Name | harvester-longhorn-1rep |
| Provisioner | driver.longhorn.io |
| Number of replicas | 1 |
| Allow volume expansion | yes |
| Reclaim policy | Delete |
Parameters (if the form exposes them as YAML/custom):
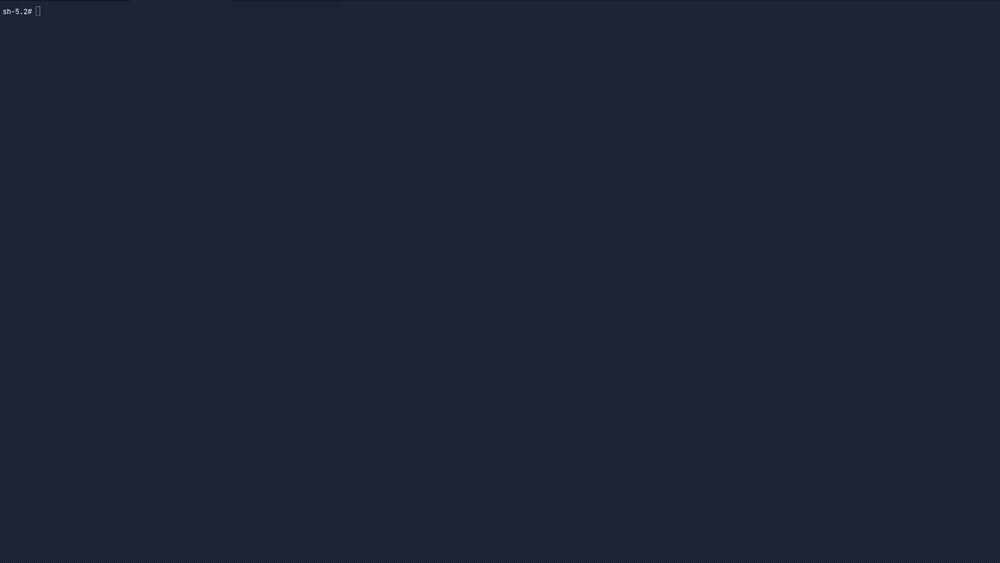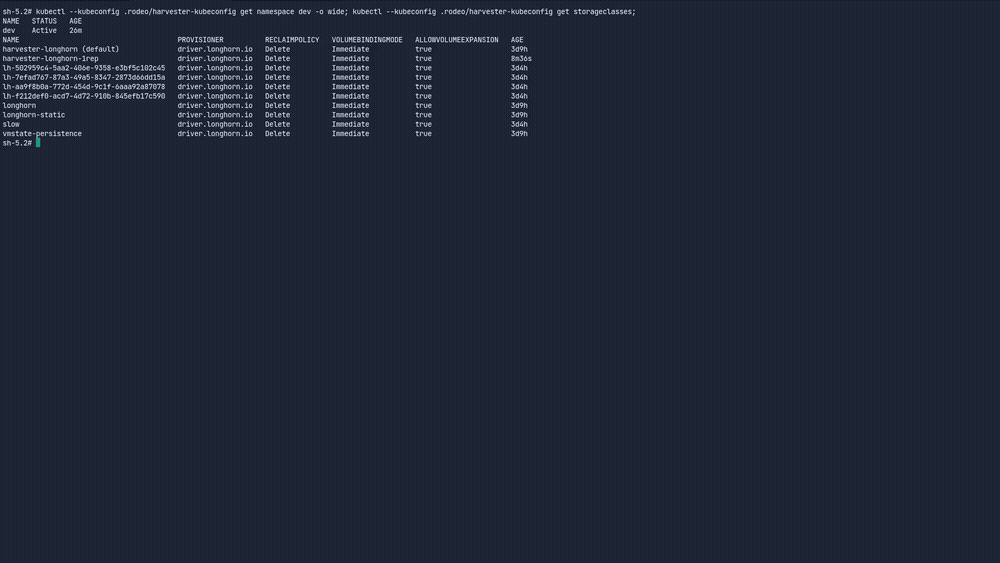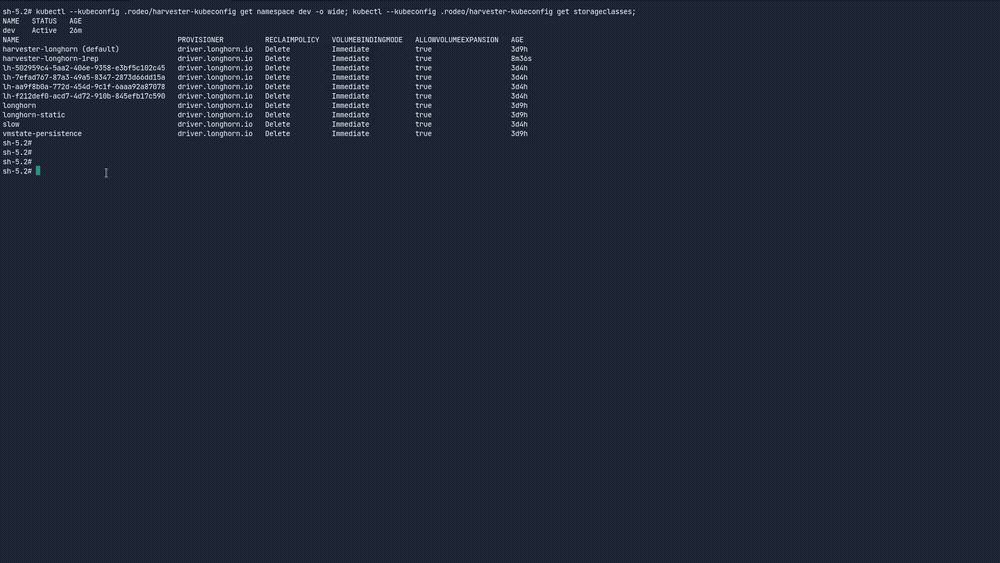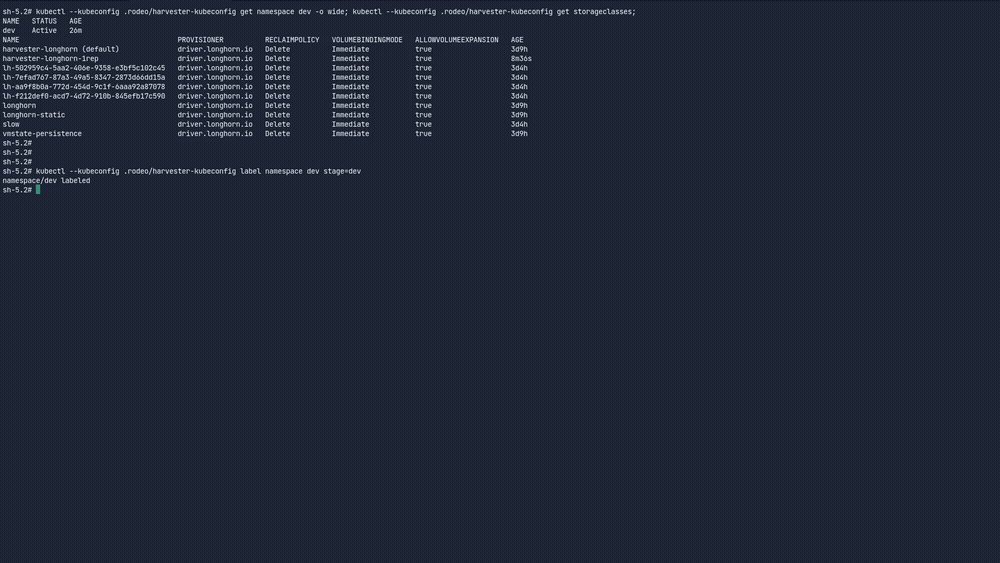
Optional: everything above is also visible through the Kubernetes API. Open the Harvester cluster terminal and run
kubectl get storageclassto see both tiers as API objects.
2.5 Confirm the production VM network
VMs need a network on the management fabric so you can SSH them from the host. Deploy automation already created it:
Networks → Virtual Machine Networks: confirm prod/service shows Active (Type UntaggedNetwork, bridged on the management fabric).
If it's ever missing (a previous run failed before this step), create it yourself:
| Field | Value |
|---|---|
| Namespace | prod |
| Name | service |
| Type | UntaggedNetwork |
| Cluster Network | mgmt |
2.6 Register an SSH key
Deploy automation left a shared lab VM key on the KVM host, at /opt/suse-virt-workshop/lab-vm-key. The two pre-created VMs already trust it, so using it here means one key opens every VM in your lab. Install it as your SSH key (skipped if you already have one) and print the public half:
test -f ~/.ssh/id_ed25519 || {
  install -d -m 700 ~/.ssh
  install -m 600 /opt/suse-virt-workshop/lab-vm-key ~/.ssh/id_ed25519
  install -m 644 /opt/suse-virt-workshop/lab-vm-key.pub ~/.ssh/id_ed25519.pub
}
cat ~/.ssh/id_ed25519.pub
Already had a key? Then the pre-created VMs won't trust it. For Exercise 4.4, use
ssh -i /opt/suse-virt-workshop/lab-vm-key ..., or paste the lab key's.pubhere instead of yours.
In Harvester: Advanced → SSH Keys → Create:
| Field | Value |
|---|---|
| Namespace | prod |
| Name | default |
| SSH Public Key | paste the .pub contents |
Later exercises select SSH Key: prod/default.
2.7 Upload a cloud image
Deploy automation already downloaded and cached an openSUSE Leap 16.0 Cloud image on the KVM host, serving it at http://192.168.122.1:8889/ so this step needs no internet access from inside the cluster. This is the -Cloud build variant specifically because it ships cloud-init, which the next step depends on — the plain -kvm-and-xen build of the same release is combustion-only and silently ignores cloud-init user-data.
Images → Create:
| Field | Value |
|---|---|
| Namespace | official-images (create the namespace if prompted) |
| Name | sles16 |
| URL | http://192.168.122.1:8889/Leap-16.0-Minimal-VM.x86_64-Cloud.qcow2 |
Wait until the image is Active (download is server-side via Longhorn, and fast since the image is already local).
No local cache? (a manual bare-metal deploy without this workshop's
custom_scripts) Use any SLES 16 or openSUSE Leap cloud qcow2 URL your lab can reach instead. Whatever you pick, confirm it ships cloud-init, not only combustion. Exercise 2.8's user-data and Exercise 3's cloud-init steps silently do nothing on an image that lacks it, and the VM still boots fine, which makes this easy to miss.
If your environment already mirrors a SLES 16 Minimal VM cloud image with cloud-init, prefer that and note the exact image name. Exercise 3 will reference whatever you upload here as the golden OS image.
2.8 Optional: cloud-init user-data template
Advanced → Cloud Config Templates → Create (User Data):
| Field | Value |
|---|---|
| Namespace | prod |
| Name | prod |
Minimal user-data (installs and starts qemu-guest-agent; SSH access itself uses the image's own default account, sles for the cached Leap 16.0 Cloud image from 2.7):
#cloud-config
package_update: true
packages:
  - qemu-guest-agent
runcmd:
  - systemctl enable --now qemu-guest-agent
Exercise 3 can select User Data Template: prod/prod.
Check your work: /opt/suse-virt-workshop/checks/check-exercise-2.sh.